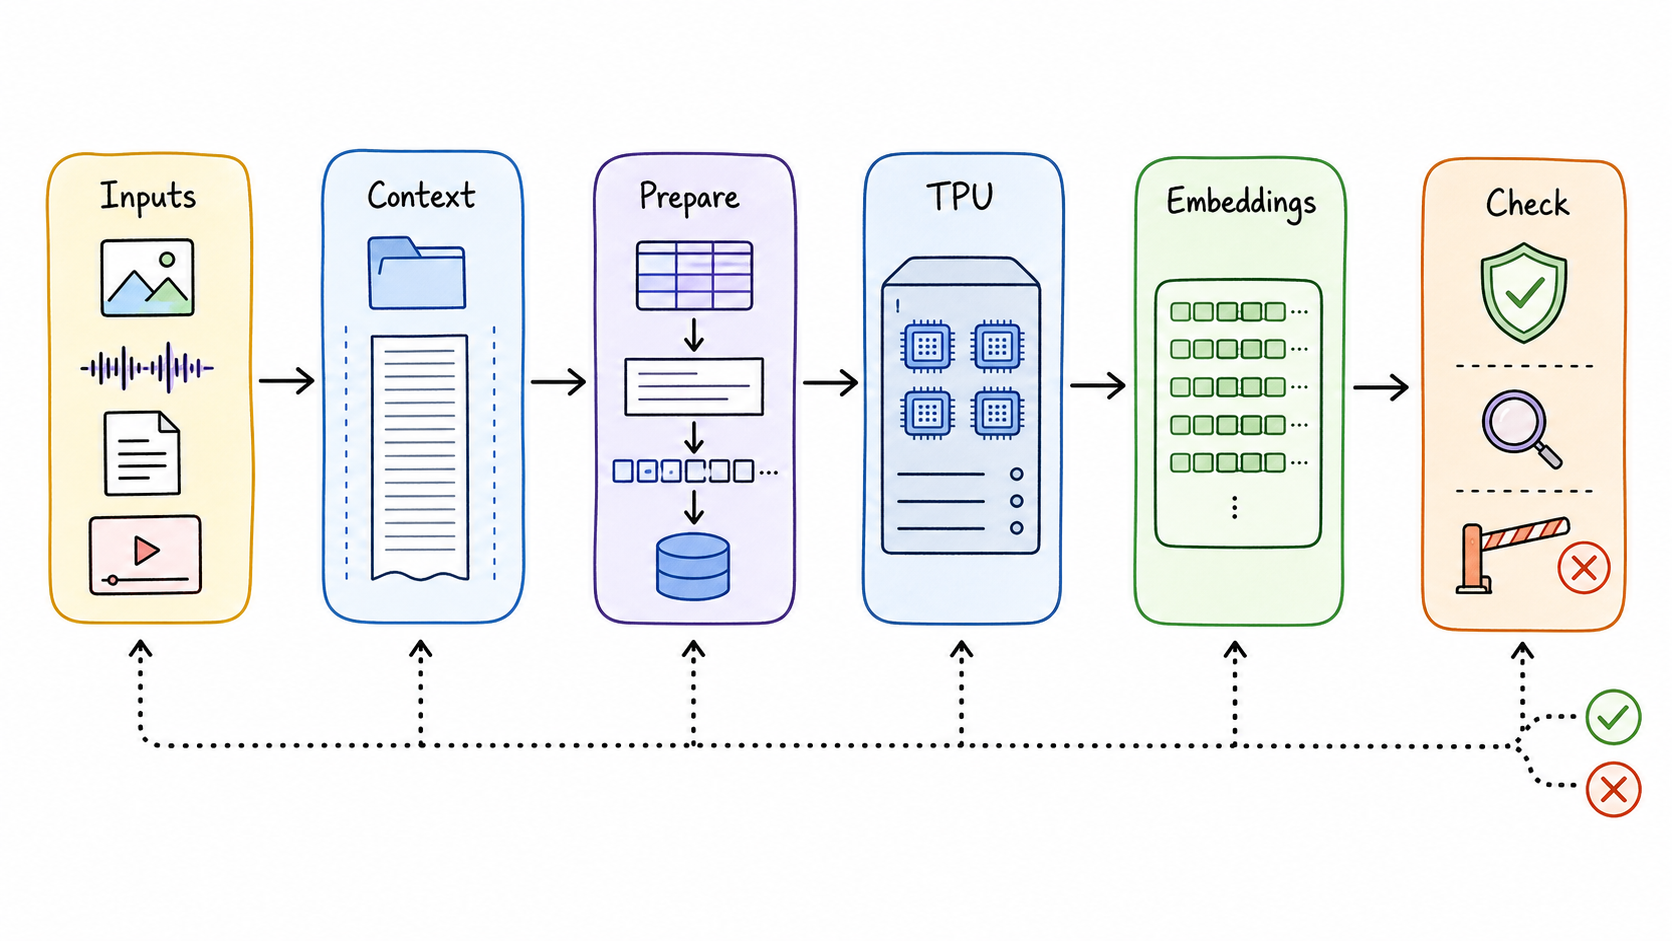
Google's Cloud TPU work treats long-context multimodal embedding inference as a precision pipeline rather than one model invocation.
Input preparation, long multimodal context, TPU execution, embedding output, and precision checks all sit on the path. Enterprise reliability therefore depends on how the whole execution chain handles batching, numerical behavior, and validation.
The practical implication is to benchmark retrieval quality and reproducibility on the deployed hardware path, not only model quality in isolation. Long-context embeddings become infrastructure when teams can measure drift, verify outputs, and keep cost and latency stable across production volume.