Field noteAug 4, 20261 min read1 source

smevals Treats Small-Model Testing As A First-Class Agent Harness

smevals is a GitHub framework for running evaluations against small and large models, making model choice a testable harness problem.

In one minute

The signal is the normalization of small-model evaluation: teams need repeatable tasks, metrics, and comparable runs before replacing large default models with cheaper local or specialized ones.

New Runtime synthesiseditorial-diagram
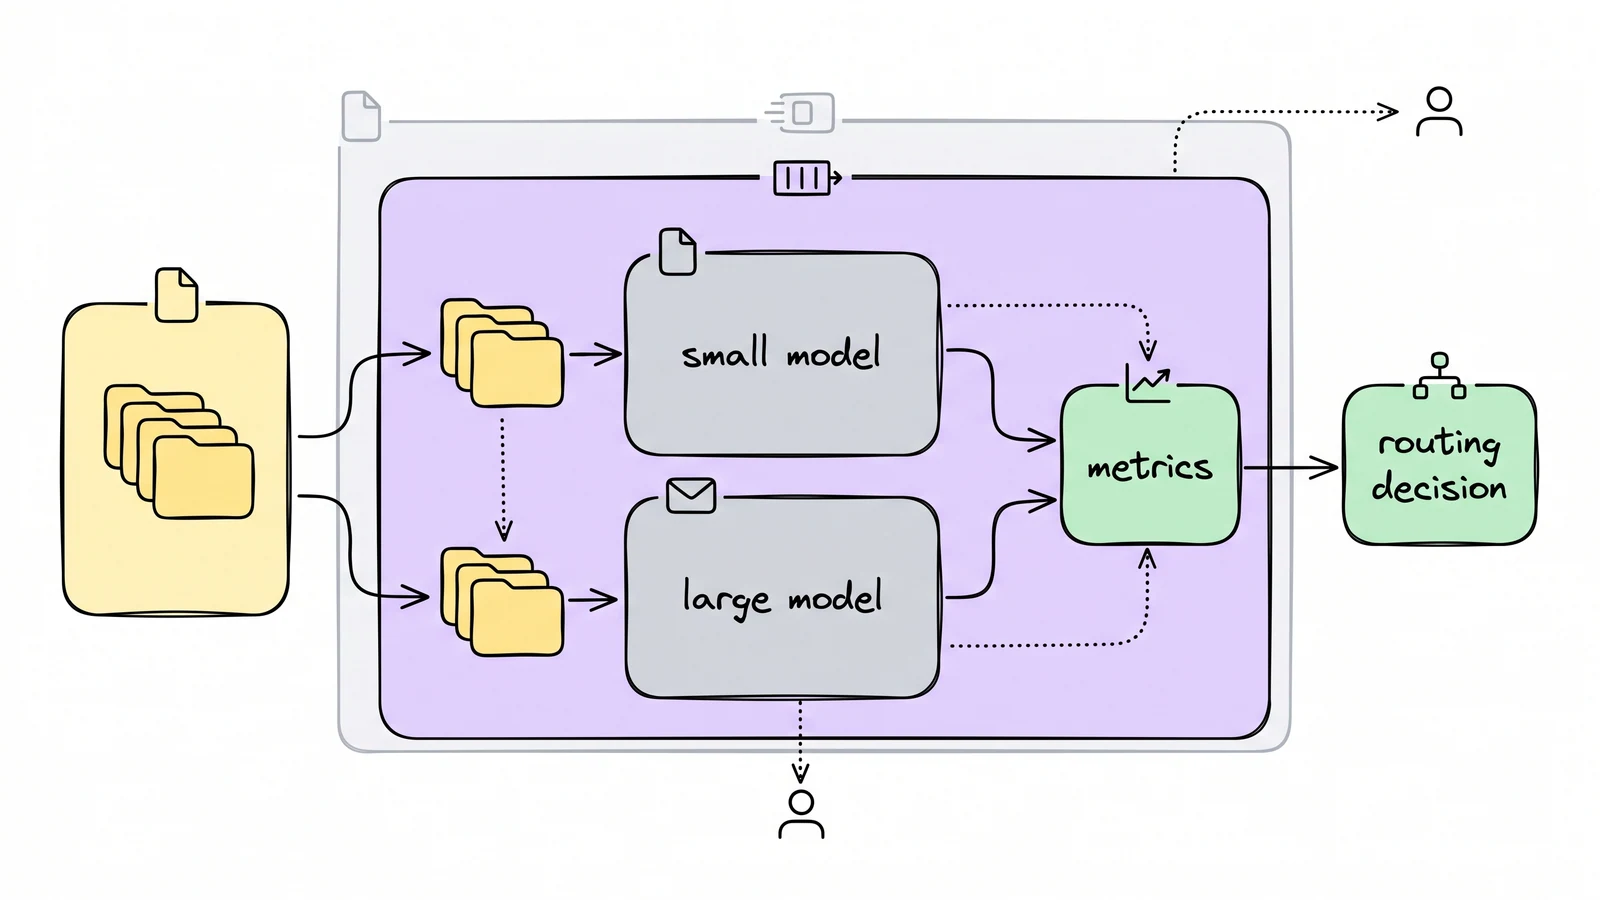
A whiteboard hub-and-spoke diagram showing a repeatable evaluation harness comparing small and large models before a model-routing decision.
New Runtime synthesis.New Runtime synthesisOriginal source ->

smevals is small on the surface, but it points at a practical model-ops problem: small models need their own evaluation harness.

The repository describes a framework for running evals against small and large models. That framing matters because small-model adoption is usually blocked less by enthusiasm and more by proof: which tasks are good enough, which fail, and where a cheap model can replace a default frontier model without quietly degrading the workflow.

For agent builders, the useful artifact is the harness. If a team can capture representative tasks, replay them across model classes, and compare results over time, model routing becomes an engineering decision instead of a taste argument.

Evidence / sources

  1. 1github.com/prime-radiant-inc/smevals
All Field Notes

Next reads

Read next

Open the graph
  1. 01topicEvalsExplore the evals topic hub.
  2. 02topicSmall ModelsExplore the small-models topic hub.
  3. 03topicAgent HarnessExplore the agent-harness topic hub.
  4. 04archiveField NotesOpen the latest editorial analysis.
  5. 05source ledgerSource LedgerInspect the public source evidence graph.
Who read this page?Machine requests, hidden until opened

Loading the privacy-safe route aggregate...

Open the JSON contract