Field noteAug 4, 20261 min read1 source

Ramp SWE-Bench Points Coding Evals Back At Production Work

Ramp published a SWE-Bench style benchmark surface, continuing the shift from abstract coding demos toward production-shaped engineering evaluation.

In one minute

The useful signal is benchmark localization: companies increasingly turn their own engineering work into eval surfaces for agent capability and workflow fit.

New Runtime synthesiseditorial-diagram
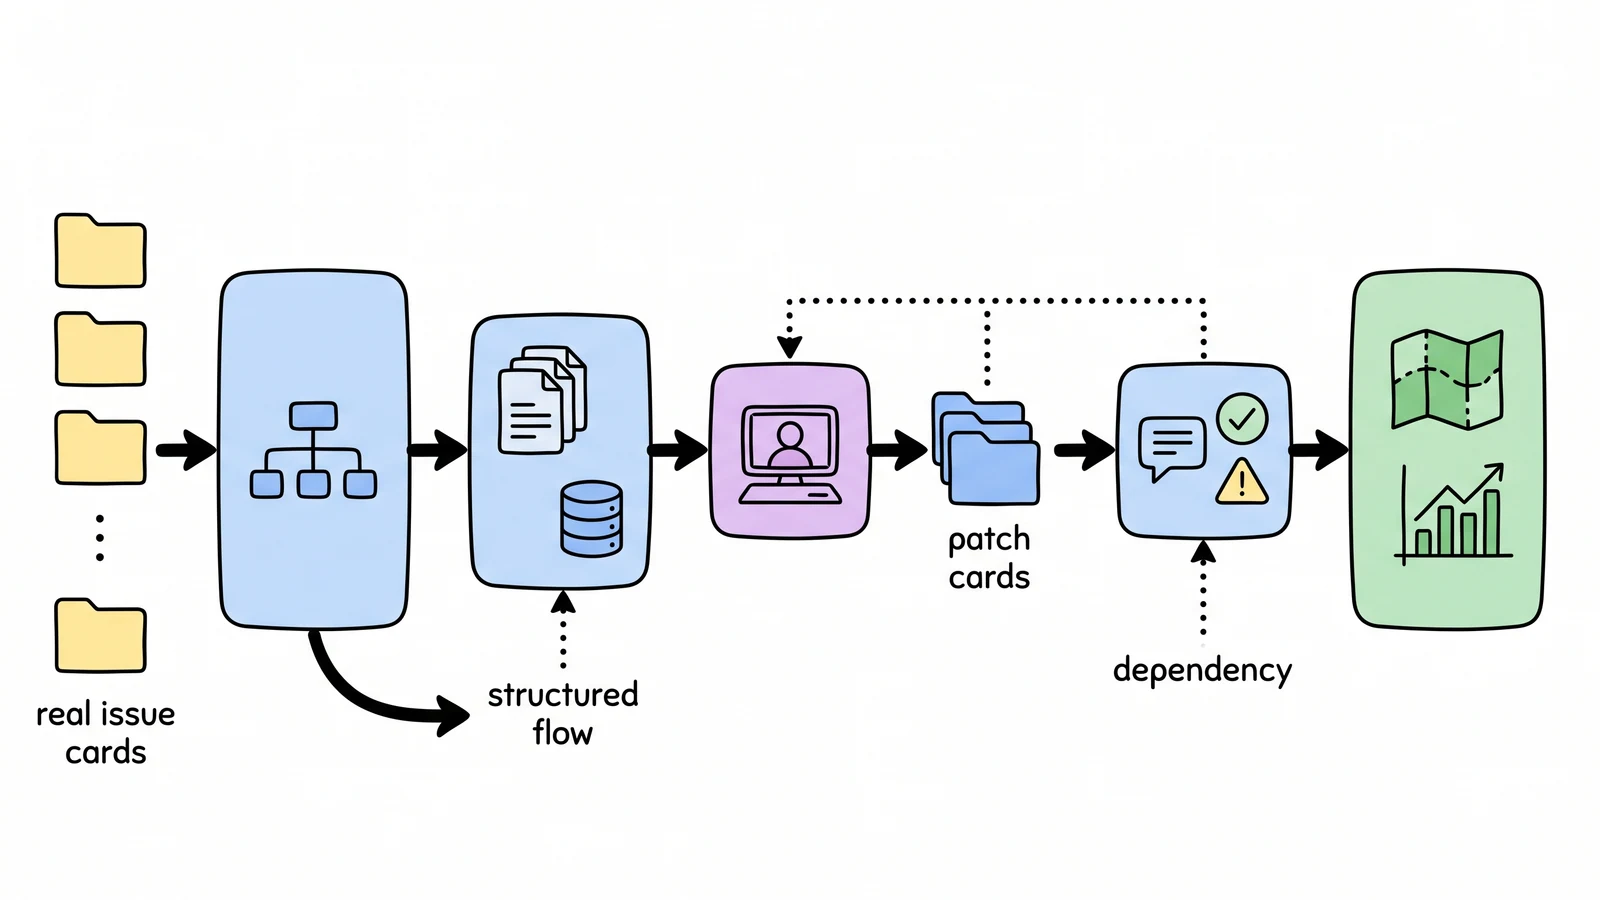
A whiteboard flow diagram showing production engineering issues becoming a SWE-Bench style harness for coding-agent patches and review signals.
New Runtime synthesis.New Runtime synthesisOriginal source ->

Ramp SWE-Bench is another sign that coding-agent evaluation is moving closer to real production work.

Generic benchmarks are useful, but they do not answer the question a company actually has: can this agent operate inside our codebase, our issue shapes, our review norms, and our failure modes? A company-specific SWE-Bench surface turns that question into a repeatable test.

The New Runtime angle is that internal evals are becoming infrastructure. As coding agents become cheaper to run and easier to plug into repositories, the scarce asset is a high-signal task set that reflects the work the organization really needs done.

Evidence / sources

  1. 1labs.ramp.com/swebench
All Field Notes

Next reads

Read next

Open the graph
  1. 01topicCoding AgentsExplore the coding-agents topic hub.
  2. 02topicEvalsExplore the evals topic hub.
  3. 03topicSoftware EngineeringExplore the software-engineering topic hub.
  4. 04archiveField NotesOpen the latest editorial analysis.
  5. 05source ledgerSource LedgerInspect the public source evidence graph.
Who read this page?Machine requests, hidden until opened

Loading the privacy-safe route aggregate...

Open the JSON contract