Field noteAug 14, 20261 min read5 sources

Evals Move From Leaderboards to Operating Diagnostics

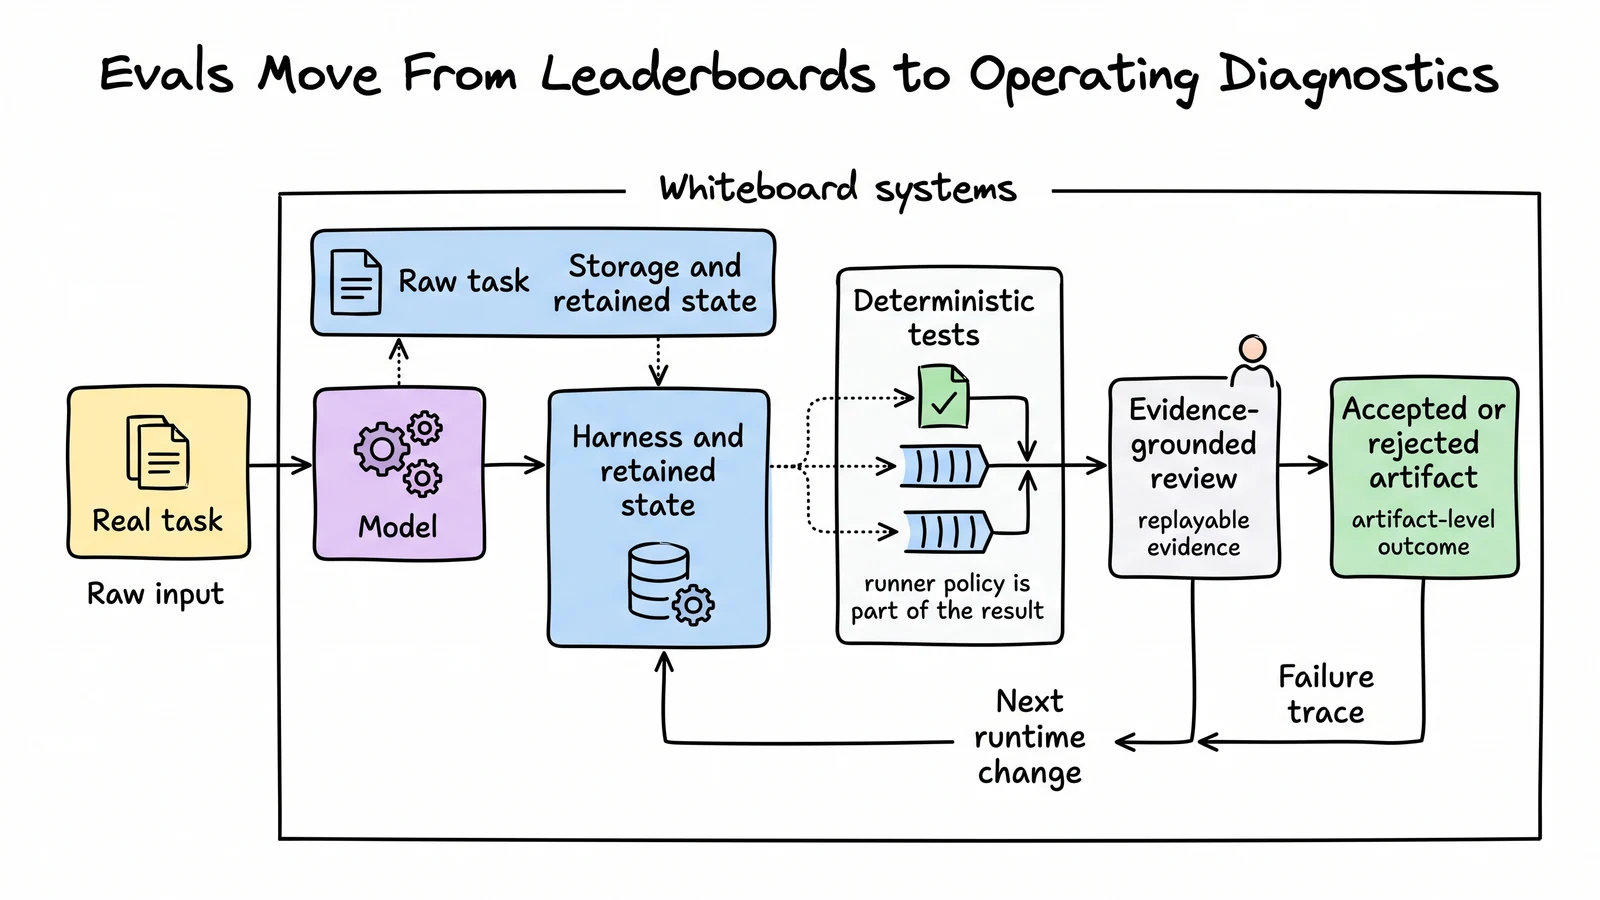
Practical evaluation increasingly measures a model together with its harness, retained state, deterministic tests, review gates, and shipped artifacts.

In one minute

A headline score without runner policy and task evidence explains less. The stronger unit is a reproducible diagnostic that can trace a failure or accepted result through the runtime.

New Runtime synthesiseditorial-diagram
New Runtime whiteboard diagram explaining evals move from leaderboards to operating diagnostics.
New Runtime synthesis from github.com.New Runtime synthesisOriginal source ->

Practical evaluation increasingly measures a model together with its harness, retained state, deterministic tests, review gates, and shipped artifacts.

New Runtime reading: A headline score without runner policy and task evidence explains less. The stronger unit is a reproducible diagnostic that can trace a failure or accepted result through the runtime.

Evidence boundary: this item uses the listed public sources and keeps vendor, author, or reporter claims attributed. The queued page is an editorial synthesis, not an independent validation of every reported metric.

Evidence / sources

  1. 1github.com/Agent-Field/pr-af
  2. 2arxiv.org/abs/2608.09802
  3. 3github.com/jerber/arc-code
  4. 4copilotkit.ai/blog/aimock-deterministic-ai-testing
  5. 5factory.ai/news/agent-effectiveness
All Field Notes

Next reads

Read next

Open the graph
  1. 01topicEvalsExplore the evals topic hub.
  2. 02topicBenchmarksExplore the benchmarks topic hub.
  3. 03topicHarness EngineeringExplore the harness-engineering topic hub.
  4. 04archiveField NotesOpen the latest editorial analysis.
  5. 05source ledgerSource LedgerInspect the public source evidence graph.
Who read this page?Machine requests, hidden until opened

Loading the privacy-safe route aggregate...

Open the JSON contract